[teamai] Push 87 resource(s) from XingfenD
This commit is contained in:

@@ -0,0 +1 @@
|
||||
XingfenD
|
||||
@@ -0,0 +1,197 @@
|
||||
# Kb Retriever Skill — Local Knowledge-Base Retriever
|
||||
|
||||
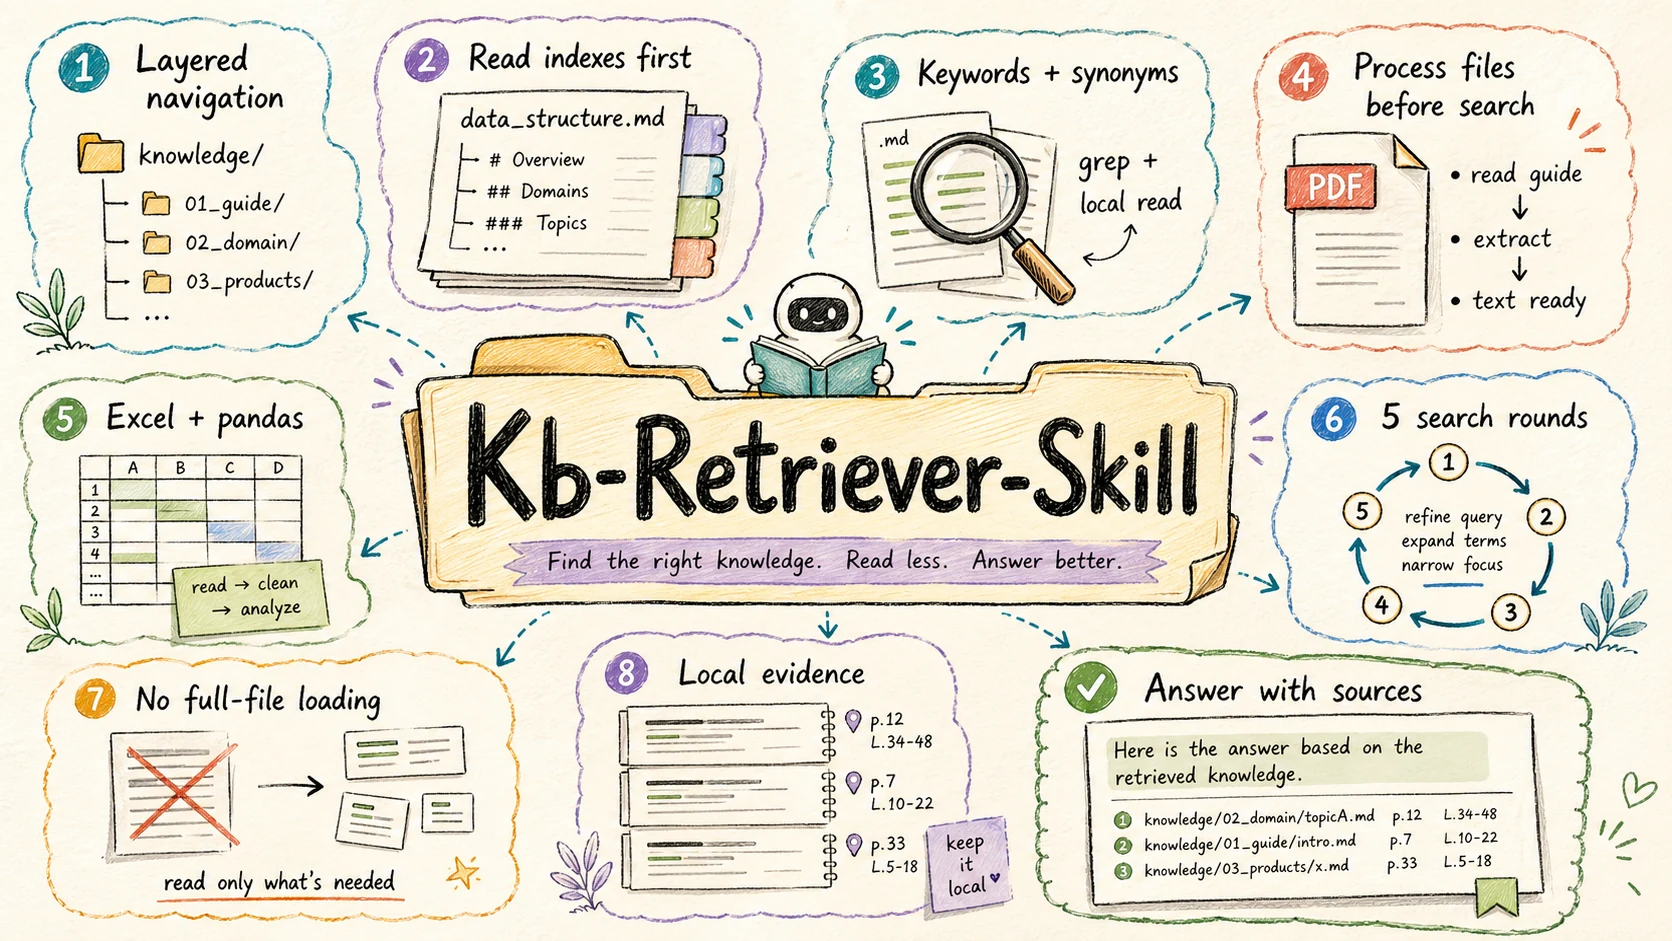
> A skill for AI agents to efficiently answer questions over a **local, multi-format knowledge directory** using hierarchical index navigation and progressive retrieval — without ever loading whole files into context.
|
||||
|
||||
[中文文档](./README.zh-CN.md) · [Back to collection root](../../README.md)
|
||||
|
||||
|
||||
|
||||
## What it does
|
||||
|
||||
Point the agent at a local directory full of mixed-format files (Markdown, PDF, Excel, …) and ask questions in natural language. The skill:
|
||||
|
||||
1. **Walks a hierarchical index** of `data_structure.md` files to figure out *which* files are likely to contain the answer.
|
||||
2. **Forces a learn-before-process step** when it hits a PDF or Excel — it must read the corresponding `references/*.md` first and use the recommended tool, instead of blindly reading the whole file.
|
||||
3. **Retrieves progressively** with `grep` + small windowed reads (offset/limit) instead of dumping entire files into context.
|
||||
4. **Iterates up to 5 rounds**, narrowing keywords each round until it has enough evidence to answer.
|
||||
|
||||
---
|
||||
|
||||
## Core features
|
||||
|
||||
- ✅ **Multi-format**: Markdown / text, PDF, Excel — extensible per file type.
|
||||
- ✅ **Hierarchical index**: each directory carries its own `data_structure.md`, forming an index tree the agent navigates.
|
||||
- ✅ **Progressive retrieval**: grep-first, windowed reads, never whole-file loads — keeps token usage low even on large corpora.
|
||||
- ✅ **Mandatory learning step**: PDF/Excel processing is gated on reading the right `references/*.md` first.
|
||||
- ✅ **Bounded iteration**: at most 5 retrieval rounds, with explicit termination conditions.
|
||||
|
||||
---
|
||||
|
||||
## Skill structure
|
||||
|
||||
```
|
||||
skills/kb-retriever/
|
||||
├── SKILL.md Main skill (frontmatter name: kb-retriever)
|
||||
├── README.md / README.zh-CN.md This document
|
||||
├── references/
|
||||
│ ├── pdf_reading.md How to handle PDFs (pdftotext / pdfplumber / pypdf)
|
||||
│ ├── excel_reading.md How to read Excel with pandas (nrows, dtype, etc.)
|
||||
│ └── excel_analysis.md How to filter / aggregate / derive metrics on Excel
|
||||
└── scripts/
|
||||
└── convert_pdf_to_images.py Convert PDF pages to images when text extraction fails
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Setting up your knowledge base
|
||||
|
||||
This skill **does not ship a knowledge base** — you bring your own. Two ways to wire it up:
|
||||
|
||||
### Default location
|
||||
|
||||
Put a `knowledge/` directory at the root of the workspace where you invoke the agent:
|
||||
|
||||
```
|
||||
your-project/
|
||||
├── .claude/skills/ or .agents/skills/
|
||||
│ └── kb-retriever/ ← this skill folder
|
||||
└── knowledge/ ← ← ← your knowledge base
|
||||
├── data_structure.md (root-level index, see template below)
|
||||
├── <domain-1>/
|
||||
│ ├── data_structure.md
|
||||
│ └── ...
|
||||
└── <domain-2>/
|
||||
└── ...
|
||||
```
|
||||
|
||||
### Custom location
|
||||
|
||||
Tell the agent which path to use in your question, e.g. *"answer from `./docs`"* or *"my knowledge base is at `/data/kb`"*. The skill will use that path instead.
|
||||
|
||||
If the default `knowledge/` does not exist and the user hasn't specified a path, the skill will ask rather than guess.
|
||||
|
||||
### `data_structure.md` template
|
||||
|
||||
Each indexed directory should carry one of these:
|
||||
|
||||
```markdown
|
||||
# [Directory name]
|
||||
|
||||
## Purpose
|
||||
What this directory is for and when it should be searched.
|
||||
|
||||
## Files
|
||||
- file1.pdf — what it contains, time / version range
|
||||
- file2.xlsx — schema summary, key columns
|
||||
- subdir/ — what lives in this subdirectory
|
||||
|
||||
## Coverage
|
||||
Time range, version, source, anything else that helps the agent prioritize.
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## How it retrieves
|
||||
|
||||
### 1. Hierarchical index navigation
|
||||
|
||||
For each directory level the skill reads `data_structure.md`, picks the most relevant child(ren) for the user's question, and recurses — so it doesn't fan out across the whole tree.
|
||||
|
||||
### 2. Learn before process (PDF / Excel)
|
||||
|
||||
When the candidate set contains a PDF or Excel file, the skill **must** first read the corresponding reference doc:
|
||||
|
||||
```
|
||||
✅ Read references/pdf_reading.md / excel_reading.md / excel_analysis.md
|
||||
✅ Understand the recommended tool & flags
|
||||
✅ Convert / extract the file with that tool
|
||||
⏭️ Then start retrieving
|
||||
```
|
||||
|
||||
Forbidden:
|
||||
|
||||
- ❌ Trying to process a PDF without reading `pdf_reading.md`
|
||||
- ❌ Trying to process an Excel without reading `excel_reading.md` / `excel_analysis.md`
|
||||
- ❌ Skipping the conversion step and grepping the raw binary
|
||||
|
||||
### 3. Progressive retrieval
|
||||
|
||||
- Don't read whole files.
|
||||
- Use `grep` to locate keywords first.
|
||||
- Read only the matching window (`limit` ≈ 200–500 lines).
|
||||
- Iterate up to 5 rounds, refining keywords.
|
||||
|
||||
### 4. Per-format tool strategy
|
||||
|
||||
| Format | Tool | Notes |
|
||||
|---|---|---|
|
||||
| Markdown / text | `grep` + windowed `read_file` | Always offset/limit; never whole-file. |
|
||||
| PDF | `pdftotext input.pdf output.txt` → `grep` on the text | **Always extract to a file**, never to stdout. Use `-f / -l` for page ranges on huge PDFs. |
|
||||
| Excel | pandas with `nrows` first to learn schema, then filtered reads | Identify key columns (id / time / category) before querying. |
|
||||
|
||||
### 5. Iteration loop
|
||||
|
||||
Each round:
|
||||
|
||||
1. Generate / update keywords
|
||||
2. Pick under-explored candidate files
|
||||
3. Run grep / windowed reads
|
||||
4. Inspect snippets
|
||||
5. Decide: enough to answer? → stop. Otherwise iterate.
|
||||
|
||||
Stops on either: answer found ✅, or 5 rounds reached ⏱️.
|
||||
|
||||
---
|
||||
|
||||
## Best practices
|
||||
|
||||
### Recommended
|
||||
|
||||
1. Always start from `data_structure.md`.
|
||||
2. Read the matching `references/*.md` *before* touching a PDF or Excel.
|
||||
3. Retrieve from the most relevant file first; expand only if needed.
|
||||
4. Use `offset` + `limit` to read precise windows.
|
||||
5. Extract PDFs to files, then grep — never paste the binary into context.
|
||||
|
||||
### Avoid
|
||||
|
||||
1. ❌ Reading entire large files in one go.
|
||||
2. ❌ Processing PDF / Excel without reading the references first.
|
||||
3. ❌ `pdftotext input.pdf -` (stdout) — eats tokens.
|
||||
4. ❌ Loading a whole Excel sheet at once.
|
||||
5. ❌ Blind search across all directories.
|
||||
|
||||
---
|
||||
|
||||
## FAQ
|
||||
|
||||
**Q1: Why force the agent to read `references/*.md` first?**
|
||||
To make sure the agent uses the right tool with the right flags — otherwise it tends to either dump huge files into context or pick a slow / broken tool.
|
||||
|
||||
**Q2: How do I handle a very large PDF?**
|
||||
Use page-ranged extraction (`pdftotext -f 1 -l 10`), grep the resulting text, then read only the matching pages.
|
||||
|
||||
**Q3: Can my knowledge base live anywhere?**
|
||||
Yes. Just say so in your question: *"answer from `/data/my-kb`"*.
|
||||
|
||||
**Q4: How do I improve retrieval accuracy?**
|
||||
Use specific keywords, narrow down with time / file-name hints, and prefer domain-specific terminology over generic words.
|
||||
|
||||
---
|
||||
|
||||
## Tool requirements
|
||||
|
||||
The skill assumes the agent has access to:
|
||||
|
||||
- `grep` — text search
|
||||
- `read_file` — windowed reads with offset / limit
|
||||
- `pdftotext` (poppler) or `pdfplumber` — PDF text extraction
|
||||
- `pandas` — Excel reads & analysis
|
||||
|
||||
`scripts/convert_pdf_to_images.py` is provided for the fallback case where text extraction yields nothing useful (scanned PDFs).
|
||||
|
||||
---
|
||||
|
||||
## License
|
||||
|
||||
MIT
|
||||
@@ -0,0 +1,197 @@
|
||||
# Kb Retriever Skill — 本地知识库检索
|
||||
|
||||
> 让 AI Agent 高效回答基于**本地多格式知识库目录**的问题。靠分层索引导航 + 渐进式检索完成,不把整文件塞进 context。
|
||||
|
||||
[English](./README.md) · [返回集合首页](../../README.zh-CN.md)
|
||||
|
||||

|
||||
|
||||
## 这个 Skill 干什么
|
||||
|
||||
把 Agent 指向一个本地的混合格式知识库目录(Markdown / PDF / Excel 等),用自然语言提问。Skill 会:
|
||||
|
||||
1. **走分层索引**:沿着每层目录的 `data_structure.md`,判断答案大概率在哪些文件里。
|
||||
2. **强制先学习再处理**:碰到 PDF / Excel 时,必须先读对应的 `references/*.md`,按推荐工具去处理,不允许蛮力直接读。
|
||||
3. **渐进式检索**:先 `grep` 定位,再用 offset/limit 局部读取,避免整文件加载。
|
||||
4. **最多 5 轮迭代**:每轮根据已读到的内容收紧关键词,直到信息足够回答。
|
||||
|
||||
---
|
||||
|
||||
## 核心特性
|
||||
|
||||
- ✅ **多格式支持**:Markdown / 文本、PDF、Excel——按文件类型可扩展。
|
||||
- ✅ **分层索引**:每层目录都带一份 `data_structure.md`,组成一棵索引树供 Agent 导航。
|
||||
- ✅ **渐进式检索**:grep 优先 + 窗口读取,从不整文件加载,大语料下也能控制住 token。
|
||||
- ✅ **强制学习机制**:PDF / Excel 的处理必须先读对应 references。
|
||||
- ✅ **有界迭代**:最多 5 轮,带明确终止条件。
|
||||
|
||||
---
|
||||
|
||||
## Skill 结构
|
||||
|
||||
```
|
||||
skills/kb-retriever/
|
||||
├── SKILL.md 主技能(frontmatter name: kb-retriever)
|
||||
├── README.md / README.zh-CN.md 本文档
|
||||
├── references/
|
||||
│ ├── pdf_reading.md PDF 处理指南(pdftotext / pdfplumber / pypdf)
|
||||
│ ├── excel_reading.md pandas 读取 Excel 的方法(nrows / dtype 等)
|
||||
│ └── excel_analysis.md Excel 的过滤 / 聚合 / 派生指标方法
|
||||
└── scripts/
|
||||
└── convert_pdf_to_images.py 当文本抽取失败时把 PDF 转图像的兜底脚本
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## 准备你的知识库
|
||||
|
||||
本 Skill **不自带**知识库——需要你自己提供。两种方式:
|
||||
|
||||
### 默认路径
|
||||
|
||||
在调用 Agent 的工作区根目录放一个 `knowledge/`:
|
||||
|
||||
```
|
||||
your-project/
|
||||
├── .claude/skills/ 或 .agents/skills/
|
||||
│ └── kb-retriever/ ← 本 Skill 目录
|
||||
└── knowledge/ ← ← ← 你的知识库
|
||||
├── data_structure.md (根级索引,模板见下)
|
||||
├── <领域-1>/
|
||||
│ ├── data_structure.md
|
||||
│ └── ...
|
||||
└── <领域-2>/
|
||||
└── ...
|
||||
```
|
||||
|
||||
### 自定义路径
|
||||
|
||||
在你的问题里直接告诉 Agent,例如"用 `./docs` 这个目录回答"或"我的知识库在 `/data/kb`",Skill 会改用你指定的路径。
|
||||
|
||||
如果默认 `knowledge/` 不存在、用户也没指定路径,Skill 会主动询问而不是瞎猜。
|
||||
|
||||
### `data_structure.md` 模板
|
||||
|
||||
每个被索引的目录都建议放一份:
|
||||
|
||||
```markdown
|
||||
# [目录名称]
|
||||
|
||||
## 用途
|
||||
本目录是干什么的、什么场景下应该被检索。
|
||||
|
||||
## 文件说明
|
||||
- file1.pdf —— 内容是什么、时间 / 版本范围
|
||||
- file2.xlsx —— 表结构概要、关键列
|
||||
- subdir/ —— 子目录用途
|
||||
|
||||
## 数据范围
|
||||
时间范围、版本、数据来源等帮助 Agent 排序优先级的信息。
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## 检索是怎么进行的
|
||||
|
||||
### 1. 分层索引导航
|
||||
|
||||
每层目录都先读 `data_structure.md`,挑出与问题最相关的子目录或文件,**再递归向下**——不会一次性铺开整棵树。
|
||||
|
||||
### 2. 先学习,再处理(PDF / Excel)
|
||||
|
||||
候选集合里出现 PDF 或 Excel 时,**必须**先读对应的 references:
|
||||
|
||||
```
|
||||
✅ 读 references/pdf_reading.md / excel_reading.md / excel_analysis.md
|
||||
✅ 理解推荐的工具与参数
|
||||
✅ 用该工具完成转换 / 抽取
|
||||
⏭️ 现在才能开始检索
|
||||
```
|
||||
|
||||
禁止行为:
|
||||
|
||||
- ❌ 没读 `pdf_reading.md` 就直接处理 PDF
|
||||
- ❌ 没读 `excel_reading.md` / `excel_analysis.md` 就直接处理 Excel
|
||||
- ❌ 跳过文件处理直接对原始 PDF / Excel 检索
|
||||
|
||||
### 3. 渐进式检索
|
||||
|
||||
- 不读整文件。
|
||||
- 先用 `grep` 定位关键词。
|
||||
- 只读匹配处的窗口(`limit` ≈ 200–500 行)。
|
||||
- 最多 5 轮,每轮收紧关键词。
|
||||
|
||||
### 4. 按文件类型选工具
|
||||
|
||||
| 格式 | 工具 | 注意 |
|
||||
|---|---|---|
|
||||
| Markdown / 文本 | `grep` + 窗口 `read_file` | 必须 offset/limit,不要整文件读。 |
|
||||
| PDF | `pdftotext input.pdf output.txt` → 对结果文本 `grep` | **必须输出到文件**,不要走 stdout。超大 PDF 用 `-f / -l` 控制页范围。 |
|
||||
| Excel | pandas,先 `nrows` 学结构,再带条件读取 | 先识别关键列(id / time / category),再查询。 |
|
||||
|
||||
### 5. 迭代循环
|
||||
|
||||
每轮:
|
||||
|
||||
1. 生成 / 更新关键词
|
||||
2. 选择尚未充分检索的候选文件
|
||||
3. 执行 grep / 局部读取
|
||||
4. 分析返回的片段
|
||||
5. 判断信息是否够回答 → 够则停止;不够进入下一轮。
|
||||
|
||||
终止条件:信息足够 ✅ 或 达到 5 轮 ⏱️。
|
||||
|
||||
---
|
||||
|
||||
## 最佳实践
|
||||
|
||||
### 推荐
|
||||
|
||||
1. 永远先从 `data_structure.md` 开始。
|
||||
2. 碰到 PDF / Excel 之前**先**读匹配的 `references/*.md`。
|
||||
3. 从最相关的文件开始检索,必要时才扩展范围。
|
||||
4. 用 `offset` + `limit` 精确控制读取窗口。
|
||||
5. PDF 先抽取到文件再 grep,**不要**把二进制塞进 context。
|
||||
|
||||
### 避免
|
||||
|
||||
1. ❌ 一次性读取大文件
|
||||
2. ❌ 没读 references 就处理 PDF / Excel
|
||||
3. ❌ `pdftotext input.pdf -`(stdout)—— 吃 token
|
||||
4. ❌ 一次性读取整张 Excel
|
||||
5. ❌ 在所有目录里盲目搜索
|
||||
|
||||
---
|
||||
|
||||
## 常见问题
|
||||
|
||||
**Q1:为什么要强制先读 `references/*.md`?**
|
||||
保证 Agent 用对的工具配对的参数——否则它要么把整个文件塞进 context,要么挑了个慢 / 坏掉的方法。
|
||||
|
||||
**Q2:超大 PDF 怎么办?**
|
||||
按页范围抽取(`pdftotext -f 1 -l 10`),对结果文本 grep,然后只读匹配页面附近的内容。
|
||||
|
||||
**Q3:知识库可以放别处吗?**
|
||||
可以,问问题时明确告诉 Agent 路径即可("用 `/data/my-kb` 回答")。
|
||||
|
||||
**Q4:怎么提高检索准确率?**
|
||||
使用更具体的关键词、缩小时间 / 文件名范围、用领域术语而非通用词汇。
|
||||
|
||||
---
|
||||
|
||||
## 工具依赖
|
||||
|
||||
本 Skill 假定 Agent 可以使用:
|
||||
|
||||
- `grep` —— 文本搜索
|
||||
- `read_file` —— 带 offset / limit 的窗口读取
|
||||
- `pdftotext`(poppler)或 `pdfplumber` —— PDF 文本抽取
|
||||
- `pandas` —— Excel 读取 / 分析
|
||||
|
||||
`scripts/convert_pdf_to_images.py` 是兜底脚本,给那种文本抽取一无所获的扫描版 PDF 用。
|
||||
|
||||
---
|
||||
|
||||
## 许可证
|
||||
|
||||
MIT
|
||||
@@ -0,0 +1,250 @@
|
||||
---
|
||||
name: kb-retriever
|
||||
description: 面向本地知识库目录的检索和问答助手。核心流程:(1)分层索引导航 (2)遇到PDF/Excel时必须先读取references学习处理方法 (3)处理文件后再检索。按文件类型组合使用 grep、Read、pdfplumber、pandas 进行渐进式检索,避免整文件加载。用户问题涉及"从知识库目录回答问题/检索信息/查资料"时使用。
|
||||
---
|
||||
|
||||
# 本地知识库检索 Skill(kb-retriever)
|
||||
|
||||
## 知识库目录说明
|
||||
|
||||
- 知识库存放在一个根目录下,包含多种文件类型(如 `.md`/`.txt`、`.pdf`、`.xlsx` 等),通常按类型或业务用途拆分为多级子目录。
|
||||
- 采用**分层目录索引文件**:
|
||||
- 根目录有一个 `data_structure.md`,说明主要的「领域目录」及其用途。
|
||||
- 每个领域目录下可以有自己的 `data_structure.md`,说明该目录下有哪些子目录/文件,以及各自用途。
|
||||
- 更深一层的子目录也可以继续有 `data_structure.md`,形成多级索引树。
|
||||
- 知识库根目录约定:
|
||||
- 默认认为知识库位于当前项目根目录下的 `knowledge/` 目录。
|
||||
- 如果用户在对话中明确指定了其他路径(例如“我的知识库在 /data/kb”或“用 ./docs 这个目录作为知识库”),则以用户指定的路径作为根目录。
|
||||
- 当默认路径 `knowledge/` 不存在或访问失败时,应向用户确认实际的知识库根目录位置,而不是随意猜测。
|
||||
- 单个业务文件可能很大:
|
||||
- 不要直接用 Read 读取整文件
|
||||
- 对 PDF、Excel 使用对应 Skill 进行结构化处理后,再结合 grep/局部读取做精细检索
|
||||
|
||||
### 定位 `knowledge` 根目录
|
||||
|
||||
- 根目录优先听用户:如果用户给了路径(如 `./docs`、`./knowledge-personal`),直接用用户提供的路径。
|
||||
- 默认根目录:否则约定根目录为当前项目下的 `knowledge/`。
|
||||
- 使用 shell 显式检查目录是否存在:优先使用 `test -d knowledge`,或退而求其次使用 `ls -d knowledge`。
|
||||
- 注意:禁止使用 `Glob "knowledge" in .` 这类模式来判断目录是否存在,`Glob` 只返回文件路径,不返回目录本身,空结果并不能区分“目录不存在”和“目录存在但为空”。
|
||||
- 只有在根目录已通过 `test -d` 等方式确认存在时,才使用 Glob 在该目录下检索内容,并把目录作为 `path`,例如:
|
||||
- 索引文件:`pattern="**/data_structure.md"`, `path="knowledge"`
|
||||
- 所有 Markdown:`pattern="**/*.md"`, `path="knowledge"`
|
||||
- 如果默认 `knowledge/` 不存在(`test -d` 失败):不要猜测其他目录,明确告诉用户未找到默认根目录,并让用户指定实际知识库路径。
|
||||
|
||||
## 关键原则:先学习,再处理
|
||||
|
||||
**遇到 PDF 或 Excel 文件时的强制检查清单**:
|
||||
|
||||
- [ ] ✅ 已读取对应的 references 文档学习处理方法
|
||||
- [ ] ✅ 已理解推荐的工具和命令
|
||||
- [ ] ✅ 已将文件处理(提取/转换)完成
|
||||
- [ ] ⏭️ 现在可以开始检索
|
||||
|
||||
**禁止行为**:
|
||||
- ❌ 在未读取 pdf_reading.md 的情况下直接尝试处理 PDF
|
||||
- ❌ 在未读取 excel_reading.md 的情况下直接尝试处理 Excel
|
||||
- ❌ 跳过文件处理步骤,直接对原始 PDF/Excel 进行检索
|
||||
|
||||
## 总体流程
|
||||
|
||||
1. 理解用户需求
|
||||
- 读用户问题,提取:
|
||||
- 主题/领域关键词(如“销售报表”“系统架构”“接口文档”)
|
||||
- 时间或范围限定(如“2023 年 Q1”“最近版本”)
|
||||
- 需要的输出类型(解释、摘要、具体字段数值等)
|
||||
- 确定知识库根目录:
|
||||
- 优先检查用户是否在问题中指定了知识库路径。
|
||||
- 否则使用默认根目录 `knowledge/`。
|
||||
- 若默认根目录不存在或目录结构异常,应向用户询问确认,而不是自行假设。
|
||||
|
||||
2. 分层查看目录索引 `data_structure.md`
|
||||
- 使用一个「当前工作目录」的概念:
|
||||
- 默认从用户指定的知识库根目录开始;如果用户未指定,则使用当前目录。
|
||||
- 在当前工作目录下,如果存在 `data_structure.md`:
|
||||
- 使用 Read 读取该文件的前若干行(例如 limit=300),必要时分段继续读取。
|
||||
- 目标:
|
||||
- 了解当前目录下有哪些子目录和文件
|
||||
- 理解每个子目录/文件的用途说明
|
||||
- 基于用户问题,挑选**最相关的若干个子目录或文件**,构成候选集合。
|
||||
- 对于候选子目录:
|
||||
- 递归进入该子目录,将其作为新的「当前工作目录」,继续查找其中的 `data_structure.md` 并重复上述过程。
|
||||
- 在递归过程中,避免一次性深入所有分支,优先沿着与问题最相关的路径向下钻取。
|
||||
- 对于候选业务文件(md/文本、PDF、Excel 等):
|
||||
- 在完成必要的目录层级探索后,收集这些文件为最终的**检索目标列表**。
|
||||
- 在优先级排序时:
|
||||
- 优先选择用途说明与问题主题高度匹配的领域目录和文件
|
||||
- 其次考虑时间/版本等约束(如果索引中有体现)
|
||||
- 通用说明类文档(如 README.md、总体设计类文档)放在较后优先级
|
||||
|
||||
3. 学习文件处理方法(遇到 PDF/Excel 时强制执行)
|
||||
- **在处理 PDF 文件前**:
|
||||
- **必须先读取** [references/pdf_reading.md](references/pdf_reading.md)(注意这个目录位于 Skills 目录下,而不是 Knowledge 目录下)学习提取方法
|
||||
- 重点了解:pdftotext 命令、pdfplumber 用法、表格提取方法
|
||||
- **在处理 Excel 文件前**:
|
||||
- **必须先读取** [references/excel_reading.md](references/excel_reading.md)学习读取方法
|
||||
- **必须先读取** [references/excel_analysis.md](references/excel_analysis.md)学习分析方法
|
||||
- 重点了解:pandas 读取、列筛选、数据过滤
|
||||
- **目的**:确保使用正确的工具和方法,避免盲目检索
|
||||
|
||||
4. 按文件类型执行处理和检索
|
||||
- 使用刚学到的方法处理文件(提取、转换、结构化)
|
||||
- 对每类候选文件,按照下面「Markdown/文本」「PDF」「Excel」策略执行
|
||||
- 总原则:
|
||||
- 优先从最相关、最精确的文件开始
|
||||
- 每个文件内都渐进式地局部检索,避免一次性加载全内容
|
||||
- 若当前文件得不到满意信息,切换到下一个候选文件
|
||||
|
||||
5. 迭代检索
|
||||
- 所有文件类型都使用统一的「多轮迭代检索机制」(见上文公共检索原则)
|
||||
|
||||
6. 答案组织与溯源
|
||||
- 汇总多轮检索得到的上下文,综合回答用户问题。
|
||||
- 尽量:
|
||||
- 给出清晰、直接的回答
|
||||
- 指出使用过的文件名(必要时包含大致位置,如章节或大概行数/页数)
|
||||
- 如果答案基于推断或信息不完全:
|
||||
- 明确标注假设与不确定性
|
||||
- 提示用户可以补充更具体的文件范围或关键词
|
||||
|
||||
## 公共检索原则
|
||||
|
||||
### 关键词选择策略
|
||||
- 从用户问题提取 3-8 个关键词(含可能的英文缩写、同义词、上位/下位词)
|
||||
- 可组合词组(如 "销售 报表"、"API 接口 超时")
|
||||
- 必要时包含业务词、技术术语、常见缩写(如 "uv"、"pv"、"GMV")
|
||||
|
||||
### grep 检索基本原则
|
||||
- 始终指定尽量精准的 include 和 path,避免搜索整个目录
|
||||
- pattern 优先尝试问题中的核心名词、术语,再尝试同义词
|
||||
- 对于每个命中,只读取匹配附近的局部区域(上下若干行)
|
||||
- 保存「文件名 + 位置信息 + 文本片段」
|
||||
|
||||
### 多轮迭代检索机制(最多 5 次)
|
||||
所有文件类型都采用统一的迭代策略:
|
||||
1. **迭代控制**
|
||||
- 维护「已尝试检索次数」计数,最多 5 次
|
||||
- 每次检索后累加计数
|
||||
2. **每轮迭代流程**
|
||||
1. 基于问题生成/更新检索关键词(可包括同义词、扩展词)
|
||||
2. 选择尚未充分检索的文件或文件部分
|
||||
3. 执行检索(grep/局部读取/专用 Skill 调用)
|
||||
4. 分析获取的上下文片段
|
||||
5. 判断是否足够回答问题
|
||||
3. **终止条件**
|
||||
- 找到足够支撑回答的上下文;或
|
||||
- 已达到 5 次尝试仍未找到合适信息
|
||||
4. **信息不足时的处理**
|
||||
- 明确告知用户信息缺失或可能不在当前知识库中
|
||||
- 提供已找到的最接近信息,并说明不确定性
|
||||
- 提示用户可以如何缩小范围(更具体的文件名、关键词、时间范围等)
|
||||
|
||||
### 注意事项
|
||||
|
||||
- 禁止第一次就直接调用:`Glob "knowledge" in .` 或任何试图用 Glob 判定目录存在性的调用,目录存在性应通过 shell 命令(如 `test -d`)检查。
|
||||
- 使用本 Skill 查询知识库时,禁止使用网络搜索等其他工具获取知识
|
||||
|
||||
## 针对不同文件类型的具体策略
|
||||
|
||||
### 1. Markdown / 文本类文件(.md, .txt, .log 等)
|
||||
|
||||
1. **候选文件选择**
|
||||
- 根据 `data_structure.md` 和文件名、路径判断相关度
|
||||
- 优先检索标题和目录类文件(如汇总文档、设计总览)
|
||||
|
||||
2. **grep 定位与局部读取**
|
||||
- 使用 Grep 工具对指定候选文件,include 限定具体后缀(如 "*.md")
|
||||
- 对于有匹配的文件,使用 Read 仅读取匹配附近的局部区域:
|
||||
- 通过行号偏移和 limit 控制读取(例如从匹配行附近往前后各读取几十行)
|
||||
- 避免整文件读取
|
||||
|
||||
3. **特殊处理**
|
||||
- 如内容仅是目录/标题,根据链接或小节名继续定位深入内容
|
||||
- 应用「多轮迭代检索机制」(见上文公共检索原则)
|
||||
|
||||
### 2. PDF 文件检索策略
|
||||
|
||||
**工作流**:
|
||||
|
||||
1. **首先:读取处理方法指南**
|
||||
- 在处理任何 PDF 之前,**必须先读取** [references/pdf_reading.md](references/pdf_reading.md)(注意这个目录位于 Skills 目录下,而不是 Knowledge 目录下)
|
||||
- 重点了解:pdftotext 命令、pdfplumber 用法、表格提取方法、快速决策表
|
||||
|
||||
2. **选择候选 PDF**
|
||||
- 根据 `data_structure.md` 中的描述,选择最相关的 1-3 个文件
|
||||
- 如果用户指明具体 PDF 文件,则优先使用该文件
|
||||
|
||||
3. **应用学到的方法提取文本**
|
||||
- 使用 pdf_reading.md 中推荐的工具(优先 pdftotext 或 pdfplumber)
|
||||
- **重要**:使用 `pdftotext input.pdf output.txt` 将文本提取到文件,不要直接输出到 stdout(避免占用大量 token)
|
||||
- 如需提取表格,使用 pdfplumber 的表格提取功能
|
||||
|
||||
4. **对提取结果执行检索**
|
||||
- 使用 grep 对提取的文本进行关键词搜索
|
||||
- 对于每个命中,提取命中附近范围的上下文(上下数十行或相邻几页)
|
||||
- 保存「文件名 + 页码/大致位置 + 文本片段」
|
||||
- 应用「多轮迭代检索机制」(见上文公共检索原则)
|
||||
|
||||
### 3. Excel 文件检索策略
|
||||
|
||||
**工作流**:
|
||||
|
||||
1. **首先:读取处理方法指南**
|
||||
- 在处理任何 Excel 之前,**必须先读取**:
|
||||
- [references/excel_reading.md](references/excel_reading.md) - 学习如何读取工作表(注意这个目录位于 Skills 目录下,而不是 Knowledge 目录下)
|
||||
- [references/excel_analysis.md](references/excel_analysis.md) - 学习如何分析数据(注意这个目录位于 Skills 目录下,而不是 Knowledge 目录下)
|
||||
- 重点了解:pandas 读取方法、列筛选、数据过滤、聚合操作
|
||||
|
||||
2. **选择候选 Excel**
|
||||
- 根据 `data_structure.md` 和文件/工作表命名,选择最相关的表
|
||||
- 优先选择包含「报表」「统计」「日志」「配置」「映射」等关键词的工作簿/工作表
|
||||
- 若用户指明具体 Excel 文件,优先使用该文件
|
||||
|
||||
3. **应用学到的方法探索结构**
|
||||
- 使用 pandas 读取前 10-50 行(使用 `nrows` 参数限制)
|
||||
- 重点掌握:列名/字段名、数据类型(数值、日期、文本)、关键字段
|
||||
- 将列名与用户问题比对,识别潜在关键字段(如「收入」「销售额」「error_code」等)
|
||||
|
||||
4. **执行数据检索和分析**
|
||||
- 使用学到的 pandas 方法进行过滤和聚合(如 `df[df['column'] == value]`)
|
||||
- 每次只读取匹配行附近的数据,避免一次性读取整表
|
||||
- 如问题包含时间范围,在检索中加入时间过滤
|
||||
- 应用「多轮迭代检索机制」(见上文公共检索原则)
|
||||
|
||||
## 与其他工具的协同
|
||||
|
||||
### PDF 处理
|
||||
- **在处理 PDF 前必须先读取** [references/pdf_reading.md](references/pdf_reading.md) 学习处理方法
|
||||
- 使用 pdfplumber/pypdf 进行文本提取、表格提取、元数据读取
|
||||
- 优先使用 pdftotext 命令行工具进行快速文本提取
|
||||
|
||||
### Excel 处理
|
||||
- **在处理 Excel 前必须先读取**:
|
||||
- [references/excel_reading.md](references/excel_reading.md) - 学习读取方法
|
||||
- [references/excel_analysis.md](references/excel_analysis.md) - 学习分析方法
|
||||
- 使用 pandas 进行数据探索、预览、过滤和分析
|
||||
|
||||
### 工具使用原则
|
||||
- **Grep**:用于按关键词在指定文件中查找行号与匹配片段,始终指定尽量精准的 include 和 path
|
||||
- **Read**:只用于局部读取文件,始终设置合理的 limit(如 200-500 行)和合适的偏移
|
||||
- **对于任何可能很大的文件**:
|
||||
- 禁止直接从头读到尾
|
||||
- 始终先通过索引、目录、关键词等方式缩小范围后再读
|
||||
|
||||
## 回答风格与错误处理
|
||||
|
||||
- 回答风格
|
||||
- 尽量用用户提问的语言(中文/英文)作答。
|
||||
- 先给出结论,再给出简要依据。
|
||||
- 如需要,可在后面列出引用的文件和大致位置,例如:
|
||||
- 来源:design/api_gateway.md 第 100 行附近
|
||||
- 来源:reports/2023_Q1_sales.xlsx Summary 工作表
|
||||
- 信息缺失或不确定时
|
||||
- 明确说明在当前知识库中没有找到完全匹配的信息或只能部分回答。
|
||||
- 不臆造事实。
|
||||
- 提示用户可以如何帮助缩小范围:
|
||||
- 指定更具体的目录/文件
|
||||
- 提供更精确的关键词或字段名
|
||||
- 指定时间/版本范围
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,15 @@
|
||||
{
|
||||
"name": "kb-retriever",
|
||||
"version": "1.0.1",
|
||||
"category": "Retrieval / Local Knowledge Base",
|
||||
"description": "Local knowledge-base retriever with progressive search. Navigates layered data_structure.md indexes, enforces learn-before-process for PDF and Excel, bounds retrieval to at most five rounds, and answers with sources.",
|
||||
"homepage": "https://github.com/ConardLi/garden-skills/tree/main/skills/kb-retriever",
|
||||
"compat": [
|
||||
"claude-code",
|
||||
"claude-ai",
|
||||
"cursor",
|
||||
"codex-cli",
|
||||
"gemini-cli",
|
||||
"opencode"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,129 @@
|
||||
# Excel 数据分析
|
||||
|
||||
> ⚠️ **使用本文档前请注意**:本文档应在实际分析 Excel 数据之前阅读,以了解正确的 pandas 分析方法。请先阅读 excel_reading.md 学习如何读取数据。
|
||||
|
||||
使用 pandas 对 Excel 数据进行常规分析操作。
|
||||
|
||||
## 快速参考
|
||||
|
||||
| 任务 | 常用方法 | 代码示例 |
|
||||
|------|----------|----------|
|
||||
| 按条件过滤 | 布尔索引 | `df[df['sales'] > 10000]` |
|
||||
| 分组聚合 | groupby | `df.groupby('region')['sales'].sum()` |
|
||||
| 排序 | sort_values | `df.sort_values('sales', ascending=False)` |
|
||||
| 计算新列 | 直接赋值 | `df['profit'] = df['revenue'] - df['cost']` |
|
||||
| 统计汇总 | describe | `df.describe()` |
|
||||
|
||||
## 分组聚合(GroupBy)
|
||||
|
||||
```python
|
||||
import pandas as pd
|
||||
|
||||
df = pd.read_excel("sales.xlsx")
|
||||
|
||||
# 按列分组并聚合
|
||||
sales_by_region = df.groupby("region")["sales"].sum()
|
||||
print(sales_by_region)
|
||||
|
||||
# 多列分组和多重聚合
|
||||
result = df.groupby(["region", "product"]).agg({
|
||||
"sales": "sum",
|
||||
"quantity": "count",
|
||||
"price": "mean"
|
||||
})
|
||||
```
|
||||
|
||||
## 数据过滤
|
||||
|
||||
```python
|
||||
# 按条件过滤行
|
||||
high_sales = df[df["sales"] > 10000]
|
||||
|
||||
# 多条件过滤
|
||||
filtered = df[(df["sales"] > 10000) & (df["region"] == "North")]
|
||||
|
||||
# 使用 isin 过滤
|
||||
selected = df[df["product"].isin(["A", "B", "C"])]
|
||||
```
|
||||
|
||||
## 派生指标计算
|
||||
|
||||
```python
|
||||
# 计算新列
|
||||
df["profit_margin"] = (df["revenue"] - df["cost"]) / df["revenue"]
|
||||
|
||||
# 百分比计算
|
||||
df["growth_rate"] = (df["current"] - df["previous"]) / df["previous"] * 100
|
||||
|
||||
# 累计求和
|
||||
df["cumulative_sales"] = df["sales"].cumsum()
|
||||
```
|
||||
|
||||
## 排序
|
||||
|
||||
```python
|
||||
# 按单列排序
|
||||
df_sorted = df.sort_values("sales", ascending=False)
|
||||
|
||||
# 按多列排序
|
||||
df_sorted = df.sort_values(["region", "sales"], ascending=[True, False])
|
||||
```
|
||||
|
||||
## 数据透视表
|
||||
|
||||
```python
|
||||
# 创建数据透视表
|
||||
pivot = pd.pivot_table(
|
||||
df,
|
||||
values="sales",
|
||||
index="region",
|
||||
columns="product",
|
||||
aggfunc="sum",
|
||||
fill_value=0
|
||||
)
|
||||
|
||||
print(pivot)
|
||||
```
|
||||
|
||||
## 统计分析
|
||||
|
||||
```python
|
||||
# 基本统计
|
||||
print(df.describe())
|
||||
|
||||
# 特定列统计
|
||||
print(df["sales"].mean())
|
||||
print(df["sales"].median())
|
||||
print(df["sales"].std())
|
||||
|
||||
# 计数统计
|
||||
print(df["category"].value_counts())
|
||||
```
|
||||
|
||||
## 数据合并
|
||||
|
||||
```python
|
||||
# 垂直合并多个 DataFrame
|
||||
combined = pd.concat([df1, df2], ignore_index=True)
|
||||
|
||||
# 按公共列合并(类似 SQL JOIN)
|
||||
merged = pd.merge(sales, customers, on="customer_id", how="left")
|
||||
```
|
||||
|
||||
## 数据清洗
|
||||
|
||||
```python
|
||||
# 删除重复行
|
||||
df = df.drop_duplicates()
|
||||
|
||||
# 处理缺失值
|
||||
df = df.fillna(0) # 填充为 0
|
||||
df = df.dropna() # 删除含缺失值的行
|
||||
|
||||
# 去除空格
|
||||
df["name"] = df["name"].str.strip()
|
||||
|
||||
# 类型转换
|
||||
df["date"] = pd.to_datetime(df["date"])
|
||||
df["amount"] = pd.to_numeric(df["amount"], errors="coerce")
|
||||
```
|
||||
@@ -0,0 +1,72 @@
|
||||
# Excel 文件读取
|
||||
|
||||
> ⚠️ **使用本文档前请注意**:本文档应在实际处理 Excel 文件之前阅读,以了解正确的 pandas 读取方法。请配合 excel_analysis.md 一起使用。
|
||||
|
||||
使用 pandas 读取 Excel 文件的核心方法。
|
||||
|
||||
## 快速入门
|
||||
|
||||
**最常用的读取方式**:
|
||||
```python
|
||||
import pandas as pd
|
||||
|
||||
# 读取第一个工作表(或指定工作表)
|
||||
df = pd.read_excel("data.xlsx", sheet_name="Sheet1")
|
||||
|
||||
# 只读取前几行查看结构
|
||||
df_preview = pd.read_excel("data.xlsx", nrows=10)
|
||||
|
||||
# 只读取需要的列(提高性能)
|
||||
df = pd.read_excel("data.xlsx", usecols=["列1", "列2", "列3"])
|
||||
```
|
||||
|
||||
## 读取单个工作表
|
||||
|
||||
```python
|
||||
import pandas as pd
|
||||
|
||||
# 读取指定工作表
|
||||
df = pd.read_excel("data.xlsx", sheet_name="Sheet1")
|
||||
|
||||
# 查看前几行
|
||||
print(df.head())
|
||||
|
||||
# 基本统计信息
|
||||
print(df.describe())
|
||||
```
|
||||
|
||||
## 读取整个工作簿的所有工作表
|
||||
|
||||
```python
|
||||
import pandas as pd
|
||||
|
||||
# 读取所有工作表
|
||||
excel_file = pd.ExcelFile("workbook.xlsx")
|
||||
|
||||
for sheet_name in excel_file.sheet_names:
|
||||
df = pd.read_excel(excel_file, sheet_name=sheet_name)
|
||||
print(f"\n{sheet_name}:")
|
||||
print(df.head())
|
||||
```
|
||||
|
||||
## 读取特定列
|
||||
|
||||
```python
|
||||
import pandas as pd
|
||||
|
||||
# 只读取指定列(提高性能)
|
||||
df = pd.read_excel("data.xlsx", usecols=["column1", "column2", "column3"])
|
||||
```
|
||||
|
||||
## 性能优化选项
|
||||
|
||||
- 使用 `usecols` 只读取需要的列
|
||||
- 使用 `dtype` 参数指定列类型以加快读取速度
|
||||
- 根据文件类型选择合适的引擎:`engine='openpyxl'` 或 `engine='xlrd'`
|
||||
|
||||
## 处理大文件
|
||||
|
||||
对于非常大的 Excel 文件,避免一次性读取整个文件:
|
||||
- 使用 `nrows` 参数限制读取的行数
|
||||
- 先读取前若干行了解数据结构
|
||||
- 按需分批处理数据
|
||||
@@ -0,0 +1,362 @@
|
||||
# PDF 读取与分析
|
||||
|
||||
> ⚠️ **使用本文档前请注意**:本文档应在实际处理 PDF 文件之前完整阅读,以选择最合适的工具和方法。不要在未阅读本文档的情况下盲目尝试处理 PDF。
|
||||
|
||||
用于从 PDF 文件中提取文本、表格和元数据的方法。
|
||||
|
||||
## 快速决策表
|
||||
|
||||
| 场景 | 推荐工具 | 原因 | 命令/代码示例 |
|
||||
|------|----------|------|--------------|
|
||||
| 纯文本提取(最常见) | pdftotext 命令 | 最快最简单 | `pdftotext input.pdf output.txt` |
|
||||
| 需要保留布局 | pdftotext -layout | 保持原始排版 | `pdftotext -layout input.pdf output.txt` |
|
||||
| 需要提取表格 | pdfplumber | 表格识别能力强 | `page.extract_tables()` |
|
||||
| 需要元数据 | pypdf | 轻量级 | `reader.metadata` |
|
||||
| 扫描PDF(图片) | OCR (pytesseract) | 无其他选择 | 先转图片再OCR |
|
||||
|
||||
## 文本提取优先级
|
||||
|
||||
**推荐优先级(从高到低)**:
|
||||
1. **pdftotext 命令行工具**(最快,适合大多数 PDF)
|
||||
2. pdfplumber(适合需要保留布局或提取表格)
|
||||
3. pypdf(轻量级,适合简单提取)
|
||||
4. OCR(仅用于扫描PDF或无法直接提取文本的情况)
|
||||
|
||||
## 快速开始:使用 pdftotext(推荐)
|
||||
|
||||
> ⚠️ **重要**:必须将输出保存到文件,不要直接输出到终端(stdout),否则会占用大量 token!
|
||||
|
||||
```bash
|
||||
# ✅ 正确:提取文本到文件(最快最简单)
|
||||
pdftotext input.pdf output.txt
|
||||
|
||||
# ✅ 正确:保留布局并输出到文件
|
||||
pdftotext -layout input.pdf output.txt
|
||||
|
||||
# ✅ 正确:提取特定页面到文件
|
||||
pdftotext -f 1 -l 5 input.pdf output.txt # 第1-5页
|
||||
|
||||
# ❌ 错误:不要使用 stdout(会占用大量 token)
|
||||
# pdftotext input.pdf -
|
||||
```
|
||||
|
||||
**使用流程**:
|
||||
1. 使用 pdftotext 提取文本到临时文件
|
||||
2. 使用 grep 或 Read 工具对生成的文本文件进行检索
|
||||
3. 只读取匹配部分的上下文,而非全文
|
||||
|
||||
如果需要在 Python 中处理:
|
||||
|
||||
```python
|
||||
from pypdf import PdfReader
|
||||
|
||||
# 读取 PDF
|
||||
reader = PdfReader("document.pdf")
|
||||
print(f"Pages: {len(reader.pages)}")
|
||||
|
||||
# 提取文本
|
||||
text = ""
|
||||
for page in reader.pages:
|
||||
text += page.extract_text()
|
||||
```
|
||||
|
||||
## Python 库
|
||||
|
||||
### pypdf - 基本文本提取
|
||||
|
||||
```python
|
||||
from pypdf import PdfReader
|
||||
|
||||
reader = PdfReader("document.pdf")
|
||||
|
||||
# 提取全部文本
|
||||
for page in reader.pages:
|
||||
text = page.extract_text()
|
||||
print(text)
|
||||
|
||||
# 提取元数据
|
||||
meta = reader.metadata
|
||||
print(f"Title: {meta.title}")
|
||||
print(f"Author: {meta.author}")
|
||||
print(f"Subject: {meta.subject}")
|
||||
print(f"Creator: {meta.creator}")
|
||||
```
|
||||
|
||||
### pdfplumber - 带布局的文本和表格提取
|
||||
|
||||
#### 提取文本(保留布局)
|
||||
|
||||
```python
|
||||
import pdfplumber
|
||||
|
||||
with pdfplumber.open("document.pdf") as pdf:
|
||||
for page in pdf.pages:
|
||||
text = page.extract_text()
|
||||
print(text)
|
||||
```
|
||||
|
||||
#### 提取表格
|
||||
|
||||
```python
|
||||
with pdfplumber.open("document.pdf") as pdf:
|
||||
for i, page in enumerate(pdf.pages):
|
||||
tables = page.extract_tables()
|
||||
for j, table in enumerate(tables):
|
||||
print(f"Table {j+1} on page {i+1}:")
|
||||
for row in table:
|
||||
print(row)
|
||||
```
|
||||
|
||||
#### 高级表格提取(转为 DataFrame)
|
||||
|
||||
```python
|
||||
import pandas as pd
|
||||
|
||||
with pdfplumber.open("document.pdf") as pdf:
|
||||
all_tables = []
|
||||
for page in pdf.pages:
|
||||
tables = page.extract_tables()
|
||||
for table in tables:
|
||||
if table: # 检查表格非空
|
||||
df = pd.DataFrame(table[1:], columns=table[0])
|
||||
all_tables.append(df)
|
||||
|
||||
# 合并所有表格
|
||||
if all_tables:
|
||||
combined_df = pd.concat(all_tables, ignore_index=True)
|
||||
combined_df.to_excel("extracted_tables.xlsx", index=False)
|
||||
```
|
||||
|
||||
#### 带坐标的精确文本提取
|
||||
|
||||
```python
|
||||
import pdfplumber
|
||||
|
||||
with pdfplumber.open("document.pdf") as pdf:
|
||||
page = pdf.pages[0]
|
||||
|
||||
# 提取所有字符及其坐标
|
||||
chars = page.chars
|
||||
for char in chars[:10]: # 前10个字符
|
||||
print(f"Char: '{char['text']}' at x:{char['x0']:.1f} y:{char['y0']:.1f}")
|
||||
|
||||
# 按边界框提取文本 (left, top, right, bottom)
|
||||
bbox_text = page.within_bbox((100, 100, 400, 200)).extract_text()
|
||||
```
|
||||
|
||||
#### 复杂表格的高级设置
|
||||
|
||||
```python
|
||||
import pdfplumber
|
||||
|
||||
with pdfplumber.open("complex_table.pdf") as pdf:
|
||||
page = pdf.pages[0]
|
||||
|
||||
# 自定义表格提取设置
|
||||
table_settings = {
|
||||
"vertical_strategy": "lines",
|
||||
"horizontal_strategy": "lines",
|
||||
"snap_tolerance": 3,
|
||||
"intersection_tolerance": 15
|
||||
}
|
||||
tables = page.extract_tables(table_settings)
|
||||
|
||||
# 可视化调试
|
||||
img = page.to_image(resolution=150)
|
||||
img.save("debug_layout.png")
|
||||
```
|
||||
|
||||
### pypdfium2 - 快速渲染和文本提取
|
||||
|
||||
```python
|
||||
import pypdfium2 as pdfium
|
||||
|
||||
# 加载 PDF
|
||||
pdf = pdfium.PdfDocument("document.pdf")
|
||||
|
||||
# 提取文本
|
||||
for i, page in enumerate(pdf):
|
||||
text = page.get_text()
|
||||
print(f"Page {i+1} text length: {len(text)} chars")
|
||||
```
|
||||
|
||||
#### 将 PDF 页面渲染为图片
|
||||
|
||||
```python
|
||||
import pypdfium2 as pdfium
|
||||
from PIL import Image
|
||||
|
||||
pdf = pdfium.PdfDocument("document.pdf")
|
||||
|
||||
# 渲染单页
|
||||
page = pdf[0] # 第一页
|
||||
bitmap = page.render(
|
||||
scale=2.0, # 高分辨率
|
||||
rotation=0 # 不旋转
|
||||
)
|
||||
|
||||
# 转换为 PIL Image
|
||||
img = bitmap.to_pil()
|
||||
img.save("page_1.png", "PNG")
|
||||
|
||||
# 处理多页
|
||||
for i, page in enumerate(pdf):
|
||||
bitmap = page.render(scale=1.5)
|
||||
img = bitmap.to_pil()
|
||||
img.save(f"page_{i+1}.jpg", "JPEG", quality=90)
|
||||
```
|
||||
|
||||
## 命令行工具
|
||||
|
||||
### pdftotext (poppler-utils)
|
||||
|
||||
> ⚠️ **性能优化**:始终输出到文件,避免占用 token
|
||||
|
||||
```bash
|
||||
# ✅ 提取文本到文件
|
||||
pdftotext input.pdf output.txt
|
||||
|
||||
# ✅ 保留布局提取到文件
|
||||
pdftotext -layout input.pdf output.txt
|
||||
|
||||
# ✅ 提取特定页面到文件
|
||||
pdftotext -f 1 -l 5 input.pdf output.txt # 第1-5页
|
||||
|
||||
# ✅ 提取带坐标的文本到 XML 文件(用于结构化数据)
|
||||
pdftotext -bbox-layout document.pdf output.xml
|
||||
|
||||
# ❌ 避免:不要省略输出文件名(会输出到 stdout)
|
||||
# pdftotext input.pdf
|
||||
```
|
||||
|
||||
### 高级图片转换 (pdftoppm)
|
||||
|
||||
```bash
|
||||
# 转换为 PNG,指定分辨率
|
||||
pdftoppm -png -r 300 document.pdf output_prefix
|
||||
|
||||
# 转换特定页面范围,高分辨率
|
||||
pdftoppm -png -r 600 -f 1 -l 3 document.pdf high_res_pages
|
||||
|
||||
# 转换为 JPEG,指定质量
|
||||
pdftoppm -jpeg -jpegopt quality=85 -r 200 document.pdf jpeg_output
|
||||
```
|
||||
|
||||
### 提取嵌入图片 (pdfimages)
|
||||
|
||||
```bash
|
||||
# 提取所有图片
|
||||
pdfimages -j input.pdf output_prefix
|
||||
|
||||
# 列出图片信息(不提取)
|
||||
pdfimages -list document.pdf
|
||||
|
||||
# 以原始格式提取
|
||||
pdfimages -all document.pdf images/img
|
||||
```
|
||||
|
||||
## OCR 提取(扫描PDF)
|
||||
|
||||
```python
|
||||
# 需要: pip install pytesseract pdf2image
|
||||
import pytesseract
|
||||
from pdf2image import convert_from_path
|
||||
|
||||
# PDF 转图片
|
||||
images = convert_from_path('scanned.pdf')
|
||||
|
||||
# OCR 每一页
|
||||
text = ""
|
||||
for i, image in enumerate(images):
|
||||
text += f"Page {i+1}:\n"
|
||||
text += pytesseract.image_to_string(image)
|
||||
text += "\n\n"
|
||||
|
||||
print(text)
|
||||
```
|
||||
|
||||
## 处理加密 PDF
|
||||
|
||||
```python
|
||||
from pypdf import PdfReader
|
||||
|
||||
try:
|
||||
reader = PdfReader("encrypted.pdf")
|
||||
if reader.is_encrypted:
|
||||
reader.decrypt("password")
|
||||
|
||||
# 解密后可正常提取文本
|
||||
for page in reader.pages:
|
||||
text = page.extract_text()
|
||||
print(text)
|
||||
except Exception as e:
|
||||
print(f"Failed to decrypt: {e}")
|
||||
```
|
||||
|
||||
```bash
|
||||
# 使用 qpdf 解密(需要知道密码)
|
||||
qpdf --password=mypassword --decrypt encrypted.pdf decrypted.pdf
|
||||
|
||||
# 检查加密状态
|
||||
qpdf --show-encryption encrypted.pdf
|
||||
```
|
||||
|
||||
## 批量处理
|
||||
|
||||
```python
|
||||
import os
|
||||
import glob
|
||||
from pypdf import PdfReader
|
||||
import logging
|
||||
|
||||
logging.basicConfig(level=logging.INFO)
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
def batch_extract_text(input_dir):
|
||||
"""批量提取文本"""
|
||||
pdf_files = glob.glob(os.path.join(input_dir, "*.pdf"))
|
||||
|
||||
for pdf_file in pdf_files:
|
||||
try:
|
||||
reader = PdfReader(pdf_file)
|
||||
text = ""
|
||||
for page in reader.pages:
|
||||
text += page.extract_text()
|
||||
|
||||
output_file = pdf_file.replace('.pdf', '.txt')
|
||||
with open(output_file, 'w', encoding='utf-8') as f:
|
||||
f.write(text)
|
||||
logger.info(f"Extracted text from: {pdf_file}")
|
||||
|
||||
except Exception as e:
|
||||
logger.error(f"Failed to extract text from {pdf_file}: {e}")
|
||||
continue
|
||||
```
|
||||
|
||||
## 性能优化
|
||||
|
||||
1. **文件输出优先**:始终将 pdftotext 输出保存到文件,然后用 grep/Read 检索,避免直接输出到终端占用大量 token
|
||||
2. **大型PDF**:使用流式方式逐页处理,避免一次性加载整个文件
|
||||
3. **文本提取**:`pdftotext` 最快;pdfplumber 适合结构化数据和表格
|
||||
4. **图片提取**:`pdfimages` 比渲染页面快得多
|
||||
5. **内存管理**:逐页或分块处理大文件
|
||||
|
||||
## 快速参考
|
||||
|
||||
| 任务 | 最佳工具 | 命令/代码 |
|
||||
|------|----------|-----------|
|
||||
| 提取文本 | pdfplumber | `page.extract_text()` |
|
||||
| 提取表格 | pdfplumber | `page.extract_tables()` |
|
||||
| 命令行提取 | pdftotext | `pdftotext -layout input.pdf` |
|
||||
| OCR 扫描PDF | pytesseract | 先转图片再OCR |
|
||||
| 提取元数据 | pypdf | `reader.metadata` |
|
||||
| PDF转图片 | pypdfium2 | `page.render()` |
|
||||
|
||||
## 可用包
|
||||
|
||||
- **pypdf** - 基本操作(BSD 许可)
|
||||
- **pdfplumber** - 文本和表格提取(MIT 许可)
|
||||
- **pypdfium2** - 快速渲染和提取(Apache/BSD 许可)
|
||||
- **pytesseract** - OCR(Apache 许可)
|
||||
- **pdf2image** - PDF转图片
|
||||
- **poppler-utils** - 命令行工具(GPL-2 许可)
|
||||
@@ -0,0 +1,35 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
from pdf2image import convert_from_path
|
||||
|
||||
|
||||
# Converts each page of a PDF to a PNG image.
|
||||
|
||||
|
||||
def convert(pdf_path, output_dir, max_dim=1000):
|
||||
images = convert_from_path(pdf_path, dpi=200)
|
||||
|
||||
for i, image in enumerate(images):
|
||||
# Scale image if needed to keep width/height under `max_dim`
|
||||
width, height = image.size
|
||||
if width > max_dim or height > max_dim:
|
||||
scale_factor = min(max_dim / width, max_dim / height)
|
||||
new_width = int(width * scale_factor)
|
||||
new_height = int(height * scale_factor)
|
||||
image = image.resize((new_width, new_height))
|
||||
|
||||
image_path = os.path.join(output_dir, f"page_{i+1}.png")
|
||||
image.save(image_path)
|
||||
print(f"Saved page {i+1} as {image_path} (size: {image.size})")
|
||||
|
||||
print(f"Converted {len(images)} pages to PNG images")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
if len(sys.argv) != 3:
|
||||
print("Usage: convert_pdf_to_images.py [input pdf] [output directory]")
|
||||
sys.exit(1)
|
||||
pdf_path = sys.argv[1]
|
||||
output_directory = sys.argv[2]
|
||||
convert(pdf_path, output_directory)
|
||||
Reference in New Issue
Block a user